Running with nthreads = 4
DataSetInfo : [dataset] : Added class "Signal"
: Add Tree sig_tree of type Signal with 1000 events
DataSetInfo : [dataset] : Added class "Background"
: Add Tree bkg_tree of type Background with 1000 events
Factory : Booking method: ␛[1mBDT␛[0m
:
: Rebuilding Dataset dataset
: Building event vectors for type 2 Signal
: Dataset[dataset] : create input formulas for tree sig_tree
: Using variable vars[0] from array expression vars of size 256
: Building event vectors for type 2 Background
: Dataset[dataset] : create input formulas for tree bkg_tree
: Using variable vars[0] from array expression vars of size 256
DataSetFactory : [dataset] : Number of events in input trees
:
:
: Number of training and testing events
: ---------------------------------------------------------------------------
: Signal -- training events : 800
: Signal -- testing events : 200
: Signal -- training and testing events: 1000
: Background -- training events : 800
: Background -- testing events : 200
: Background -- training and testing events: 1000
:
Factory : Booking method: ␛[1mTMVA_DNN_CPU␛[0m
:
: Parsing option string:
: ... "!H:V:ErrorStrategy=CROSSENTROPY:VarTransform=None:WeightInitialization=XAVIER:Layout=DENSE|100|RELU,BNORM,DENSE|100|RELU,BNORM,DENSE|100|RELU,BNORM,DENSE|100|RELU,DENSE|1|LINEAR:TrainingStrategy=LearningRate=1e-3,Momentum=0.9,Repetitions=1,ConvergenceSteps=5,BatchSize=100,TestRepetitions=1,WeightDecay=1e-4,Regularization=None,Optimizer=ADAM,DropConfig=0.0+0.0+0.0+0.,MaxEpochs=10:Architecture=CPU"
: The following options are set:
: - By User:
: <none>
: - Default:
: Boost_num: "0" [Number of times the classifier will be boosted]
: Parsing option string:
: ... "!H:V:ErrorStrategy=CROSSENTROPY:VarTransform=None:WeightInitialization=XAVIER:Layout=DENSE|100|RELU,BNORM,DENSE|100|RELU,BNORM,DENSE|100|RELU,BNORM,DENSE|100|RELU,DENSE|1|LINEAR:TrainingStrategy=LearningRate=1e-3,Momentum=0.9,Repetitions=1,ConvergenceSteps=5,BatchSize=100,TestRepetitions=1,WeightDecay=1e-4,Regularization=None,Optimizer=ADAM,DropConfig=0.0+0.0+0.0+0.,MaxEpochs=10:Architecture=CPU"
: The following options are set:
: - By User:
: V: "True" [Verbose output (short form of "VerbosityLevel" below - overrides the latter one)]
: VarTransform: "None" [List of variable transformations performed before training, e.g., "D_Background,P_Signal,G,N_AllClasses" for: "Decorrelation, PCA-transformation, Gaussianisation, Normalisation, each for the given class of events ('AllClasses' denotes all events of all classes, if no class indication is given, 'All' is assumed)"]
: H: "False" [Print method-specific help message]
: Layout: "DENSE|100|RELU,BNORM,DENSE|100|RELU,BNORM,DENSE|100|RELU,BNORM,DENSE|100|RELU,DENSE|1|LINEAR" [Layout of the network.]
: ErrorStrategy: "CROSSENTROPY" [Loss function: Mean squared error (regression) or cross entropy (binary classification).]
: WeightInitialization: "XAVIER" [Weight initialization strategy]
: Architecture: "CPU" [Which architecture to perform the training on.]
: TrainingStrategy: "LearningRate=1e-3,Momentum=0.9,Repetitions=1,ConvergenceSteps=5,BatchSize=100,TestRepetitions=1,WeightDecay=1e-4,Regularization=None,Optimizer=ADAM,DropConfig=0.0+0.0+0.0+0.,MaxEpochs=10" [Defines the training strategies.]
: - Default:
: VerbosityLevel: "Default" [Verbosity level]
: CreateMVAPdfs: "False" [Create PDFs for classifier outputs (signal and background)]
: IgnoreNegWeightsInTraining: "False" [Events with negative weights are ignored in the training (but are included for testing and performance evaluation)]
: InputLayout: "0|0|0" [The Layout of the input]
: BatchLayout: "0|0|0" [The Layout of the batch]
: RandomSeed: "0" [Random seed used for weight initialization and batch shuffling]
: ValidationSize: "20%" [Part of the training data to use for validation. Specify as 0.2 or 20% to use a fifth of the data set as validation set. Specify as 100 to use exactly 100 events. (Default: 20%)]
: Will now use the CPU architecture with BLAS and IMT support !
Factory : Booking method: ␛[1mTMVA_CNN_CPU␛[0m
:
: Parsing option string:
: ... "!H:V:ErrorStrategy=CROSSENTROPY:VarTransform=None:WeightInitialization=XAVIER:InputLayout=1|16|16:Layout=CONV|10|3|3|1|1|1|1|RELU,BNORM,CONV|10|3|3|1|1|1|1|RELU,MAXPOOL|2|2|1|1,RESHAPE|FLAT,DENSE|100|RELU,DENSE|1|LINEAR:TrainingStrategy=LearningRate=1e-3,Momentum=0.9,Repetitions=1,ConvergenceSteps=5,BatchSize=100,TestRepetitions=1,WeightDecay=1e-4,Regularization=None,Optimizer=ADAM,DropConfig=0.0+0.0+0.0+0.0,MaxEpochs=10:Architecture=CPU"
: The following options are set:
: - By User:
: <none>
: - Default:
: Boost_num: "0" [Number of times the classifier will be boosted]
: Parsing option string:
: ... "!H:V:ErrorStrategy=CROSSENTROPY:VarTransform=None:WeightInitialization=XAVIER:InputLayout=1|16|16:Layout=CONV|10|3|3|1|1|1|1|RELU,BNORM,CONV|10|3|3|1|1|1|1|RELU,MAXPOOL|2|2|1|1,RESHAPE|FLAT,DENSE|100|RELU,DENSE|1|LINEAR:TrainingStrategy=LearningRate=1e-3,Momentum=0.9,Repetitions=1,ConvergenceSteps=5,BatchSize=100,TestRepetitions=1,WeightDecay=1e-4,Regularization=None,Optimizer=ADAM,DropConfig=0.0+0.0+0.0+0.0,MaxEpochs=10:Architecture=CPU"
: The following options are set:
: - By User:
: V: "True" [Verbose output (short form of "VerbosityLevel" below - overrides the latter one)]
: VarTransform: "None" [List of variable transformations performed before training, e.g., "D_Background,P_Signal,G,N_AllClasses" for: "Decorrelation, PCA-transformation, Gaussianisation, Normalisation, each for the given class of events ('AllClasses' denotes all events of all classes, if no class indication is given, 'All' is assumed)"]
: H: "False" [Print method-specific help message]
: InputLayout: "1|16|16" [The Layout of the input]
: Layout: "CONV|10|3|3|1|1|1|1|RELU,BNORM,CONV|10|3|3|1|1|1|1|RELU,MAXPOOL|2|2|1|1,RESHAPE|FLAT,DENSE|100|RELU,DENSE|1|LINEAR" [Layout of the network.]
: ErrorStrategy: "CROSSENTROPY" [Loss function: Mean squared error (regression) or cross entropy (binary classification).]
: WeightInitialization: "XAVIER" [Weight initialization strategy]
: Architecture: "CPU" [Which architecture to perform the training on.]
: TrainingStrategy: "LearningRate=1e-3,Momentum=0.9,Repetitions=1,ConvergenceSteps=5,BatchSize=100,TestRepetitions=1,WeightDecay=1e-4,Regularization=None,Optimizer=ADAM,DropConfig=0.0+0.0+0.0+0.0,MaxEpochs=10" [Defines the training strategies.]
: - Default:
: VerbosityLevel: "Default" [Verbosity level]
: CreateMVAPdfs: "False" [Create PDFs for classifier outputs (signal and background)]
: IgnoreNegWeightsInTraining: "False" [Events with negative weights are ignored in the training (but are included for testing and performance evaluation)]
: BatchLayout: "0|0|0" [The Layout of the batch]
: RandomSeed: "0" [Random seed used for weight initialization and batch shuffling]
: ValidationSize: "20%" [Part of the training data to use for validation. Specify as 0.2 or 20% to use a fifth of the data set as validation set. Specify as 100 to use exactly 100 events. (Default: 20%)]
: Will now use the CPU architecture with BLAS and IMT support !
Factory : ␛[1mTrain all methods␛[0m
Factory : Train method: BDT for Classification
:
BDT : #events: (reweighted) sig: 800 bkg: 800
: #events: (unweighted) sig: 800 bkg: 800
: Training 400 Decision Trees ... patience please
: Elapsed time for training with 1600 events: 1.32 sec
BDT : [dataset] : Evaluation of BDT on training sample (1600 events)
: Elapsed time for evaluation of 1600 events: 0.0152 sec
: Creating xml weight file: ␛[0;36mdataset/weights/TMVA_CNN_Classification_BDT.weights.xml␛[0m
: Creating standalone class: ␛[0;36mdataset/weights/TMVA_CNN_Classification_BDT.class.C␛[0m
: TMVA_CNN_ClassificationOutput.root:/dataset/Method_BDT/BDT
Factory : Training finished
:
Factory : Train method: TMVA_DNN_CPU for Classification
:
: Start of deep neural network training on CPU using MT, nthreads = 4
:
: ***** Deep Learning Network *****
DEEP NEURAL NETWORK: Depth = 8 Input = ( 1, 1, 256 ) Batch size = 100 Loss function = C
Layer 0 DENSE Layer: ( Input = 256 , Width = 100 ) Output = ( 1 , 100 , 100 ) Activation Function = Relu
Layer 1 BATCH NORM Layer: Input/Output = ( 100 , 100 , 1 ) Norm dim = 100 axis = -1
Layer 2 DENSE Layer: ( Input = 100 , Width = 100 ) Output = ( 1 , 100 , 100 ) Activation Function = Relu
Layer 3 BATCH NORM Layer: Input/Output = ( 100 , 100 , 1 ) Norm dim = 100 axis = -1
Layer 4 DENSE Layer: ( Input = 100 , Width = 100 ) Output = ( 1 , 100 , 100 ) Activation Function = Relu
Layer 5 BATCH NORM Layer: Input/Output = ( 100 , 100 , 1 ) Norm dim = 100 axis = -1
Layer 6 DENSE Layer: ( Input = 100 , Width = 100 ) Output = ( 1 , 100 , 100 ) Activation Function = Relu
Layer 7 DENSE Layer: ( Input = 100 , Width = 1 ) Output = ( 1 , 100 , 1 ) Activation Function = Identity
: Using 1280 events for training and 320 for testing
: Compute initial loss on the validation data
: Training phase 1 of 1: Optimizer ADAM (beta1=0.9,beta2=0.999,eps=1e-07) Learning rate = 0.001 regularization 0 minimum error = 97.9804
: --------------------------------------------------------------
: Epoch | Train Err. Val. Err. t(s)/epoch t(s)/Loss nEvents/s Conv. Steps
: --------------------------------------------------------------
: Start epoch iteration ...
: 1 Minimum Test error found - save the configuration
: 1 | 0.97789 1.02717 0.109088 0.0104223 12162.3 0
: 2 Minimum Test error found - save the configuration
: 2 | 0.695186 0.761404 0.105793 0.0104127 12581.2 0
: 3 Minimum Test error found - save the configuration
: 3 | 0.595855 0.705128 0.103868 0.0103717 12834.7 0
: 4 Minimum Test error found - save the configuration
: 4 | 0.507262 0.666449 0.106089 0.010461 12548.6 0
: 5 | 0.46224 0.760399 0.105422 0.0100278 12579.4 1
: 6 | 0.409559 0.697006 0.103541 0.00989805 12814.7 2
: 7 | 0.368154 0.737252 0.104479 0.00977006 12670.4 3
: 8 | 0.333484 0.714974 0.105165 0.00983921 12588.4 4
: 9 | 0.279694 0.709673 0.102578 0.00995843 12956.3 5
: 10 | 0.23877 0.724385 0.108403 0.0108139 12296.5 6
:
: Elapsed time for training with 1600 events: 1.08 sec
: Evaluate deep neural network on CPU using batches with size = 100
:
TMVA_DNN_CPU : [dataset] : Evaluation of TMVA_DNN_CPU on training sample (1600 events)
: Elapsed time for evaluation of 1600 events: 0.0532 sec
: Creating xml weight file: ␛[0;36mdataset/weights/TMVA_CNN_Classification_TMVA_DNN_CPU.weights.xml␛[0m
: Creating standalone class: ␛[0;36mdataset/weights/TMVA_CNN_Classification_TMVA_DNN_CPU.class.C␛[0m
Factory : Training finished
:
Factory : Train method: TMVA_CNN_CPU for Classification
:
: Start of deep neural network training on CPU using MT, nthreads = 4
:
: ***** Deep Learning Network *****
DEEP NEURAL NETWORK: Depth = 7 Input = ( 1, 16, 16 ) Batch size = 100 Loss function = C
Layer 0 CONV LAYER: ( W = 16 , H = 16 , D = 10 ) Filter ( W = 3 , H = 3 ) Output = ( 100 , 10 , 10 , 256 ) Activation Function = Relu
Layer 1 BATCH NORM Layer: Input/Output = ( 10 , 256 , 100 ) Norm dim = 10 axis = 1
Layer 2 CONV LAYER: ( W = 16 , H = 16 , D = 10 ) Filter ( W = 3 , H = 3 ) Output = ( 100 , 10 , 10 , 256 ) Activation Function = Relu
Layer 3 POOL Layer: ( W = 15 , H = 15 , D = 10 ) Filter ( W = 2 , H = 2 ) Output = ( 100 , 10 , 10 , 225 )
Layer 4 RESHAPE Layer Input = ( 10 , 15 , 15 ) Output = ( 1 , 100 , 2250 )
Layer 5 DENSE Layer: ( Input = 2250 , Width = 100 ) Output = ( 1 , 100 , 100 ) Activation Function = Relu
Layer 6 DENSE Layer: ( Input = 100 , Width = 1 ) Output = ( 1 , 100 , 1 ) Activation Function = Identity
: Using 1280 events for training and 320 for testing
: Compute initial loss on the validation data
: Training phase 1 of 1: Optimizer ADAM (beta1=0.9,beta2=0.999,eps=1e-07) Learning rate = 0.001 regularization 0 minimum error = 80.0188
: --------------------------------------------------------------
: Epoch | Train Err. Val. Err. t(s)/epoch t(s)/Loss nEvents/s Conv. Steps
: --------------------------------------------------------------
: Start epoch iteration ...
: 1 Minimum Test error found - save the configuration
: 1 | 1.89258 0.742912 0.773325 0.0654714 1695.27 0
: 2 | 0.807097 0.747124 0.788373 0.0635554 1655.59 1
: 3 Minimum Test error found - save the configuration
: 3 | 0.720682 0.685629 0.789663 0.0652075 1656.42 0
: 4 Minimum Test error found - save the configuration
: 4 | 0.688706 0.664297 0.774526 0.0646032 1690.32 0
: 5 Minimum Test error found - save the configuration
: 5 | 0.673585 0.64596 0.779368 0.0651232 1680.1 0
: 6 | 0.647398 0.701762 0.752554 0.0632543 1740.9 1
: 7 Minimum Test error found - save the configuration
: 7 | 0.616435 0.609216 0.784186 0.0647153 1667.89 0
: 8 | 0.580311 0.61972 0.761201 0.0637845 1720.64 1
: 9 Minimum Test error found - save the configuration
: 9 | 0.560355 0.587013 0.770235 0.0659047 1703.75 0
: 10 Minimum Test error found - save the configuration
: 10 | 0.518301 0.584683 0.786038 0.0755966 1689.09 0
:
: Elapsed time for training with 1600 events: 7.83 sec
: Evaluate deep neural network on CPU using batches with size = 100
:
TMVA_CNN_CPU : [dataset] : Evaluation of TMVA_CNN_CPU on training sample (1600 events)
: Elapsed time for evaluation of 1600 events: 0.342 sec
: Creating xml weight file: ␛[0;36mdataset/weights/TMVA_CNN_Classification_TMVA_CNN_CPU.weights.xml␛[0m
: Creating standalone class: ␛[0;36mdataset/weights/TMVA_CNN_Classification_TMVA_CNN_CPU.class.C␛[0m
Factory : Training finished
:
: Ranking input variables (method specific)...
BDT : Ranking result (top variable is best ranked)
: --------------------------------------
: Rank : Variable : Variable Importance
: --------------------------------------
: 1 : vars : 1.038e-02
: 2 : vars : 8.789e-03
: 3 : vars : 8.637e-03
: 4 : vars : 7.939e-03
: 5 : vars : 7.889e-03
: 6 : vars : 7.792e-03
: 7 : vars : 7.701e-03
: 8 : vars : 7.609e-03
: 9 : vars : 7.570e-03
: 10 : vars : 7.550e-03
: 11 : vars : 7.476e-03
: 12 : vars : 7.275e-03
: 13 : vars : 7.226e-03
: 14 : vars : 7.214e-03
: 15 : vars : 7.166e-03
: 16 : vars : 7.159e-03
: 17 : vars : 7.097e-03
: 18 : vars : 7.068e-03
: 19 : vars : 6.946e-03
: 20 : vars : 6.908e-03
: 21 : vars : 6.827e-03
: 22 : vars : 6.732e-03
: 23 : vars : 6.673e-03
: 24 : vars : 6.601e-03
: 25 : vars : 6.482e-03
: 26 : vars : 6.298e-03
: 27 : vars : 6.292e-03
: 28 : vars : 6.273e-03
: 29 : vars : 6.196e-03
: 30 : vars : 6.195e-03
: 31 : vars : 6.181e-03
: 32 : vars : 6.095e-03
: 33 : vars : 6.086e-03
: 34 : vars : 6.056e-03
: 35 : vars : 6.054e-03
: 36 : vars : 5.965e-03
: 37 : vars : 5.944e-03
: 38 : vars : 5.914e-03
: 39 : vars : 5.911e-03
: 40 : vars : 5.881e-03
: 41 : vars : 5.865e-03
: 42 : vars : 5.864e-03
: 43 : vars : 5.815e-03
: 44 : vars : 5.793e-03
: 45 : vars : 5.746e-03
: 46 : vars : 5.706e-03
: 47 : vars : 5.546e-03
: 48 : vars : 5.527e-03
: 49 : vars : 5.495e-03
: 50 : vars : 5.465e-03
: 51 : vars : 5.447e-03
: 52 : vars : 5.445e-03
: 53 : vars : 5.389e-03
: 54 : vars : 5.384e-03
: 55 : vars : 5.374e-03
: 56 : vars : 5.360e-03
: 57 : vars : 5.355e-03
: 58 : vars : 5.308e-03
: 59 : vars : 5.293e-03
: 60 : vars : 5.289e-03
: 61 : vars : 5.255e-03
: 62 : vars : 5.243e-03
: 63 : vars : 5.232e-03
: 64 : vars : 5.178e-03
: 65 : vars : 5.127e-03
: 66 : vars : 5.081e-03
: 67 : vars : 5.078e-03
: 68 : vars : 5.077e-03
: 69 : vars : 5.058e-03
: 70 : vars : 5.020e-03
: 71 : vars : 4.898e-03
: 72 : vars : 4.822e-03
: 73 : vars : 4.819e-03
: 74 : vars : 4.793e-03
: 75 : vars : 4.784e-03
: 76 : vars : 4.781e-03
: 77 : vars : 4.755e-03
: 78 : vars : 4.751e-03
: 79 : vars : 4.735e-03
: 80 : vars : 4.694e-03
: 81 : vars : 4.682e-03
: 82 : vars : 4.675e-03
: 83 : vars : 4.649e-03
: 84 : vars : 4.601e-03
: 85 : vars : 4.579e-03
: 86 : vars : 4.570e-03
: 87 : vars : 4.547e-03
: 88 : vars : 4.545e-03
: 89 : vars : 4.508e-03
: 90 : vars : 4.491e-03
: 91 : vars : 4.475e-03
: 92 : vars : 4.451e-03
: 93 : vars : 4.444e-03
: 94 : vars : 4.441e-03
: 95 : vars : 4.433e-03
: 96 : vars : 4.426e-03
: 97 : vars : 4.381e-03
: 98 : vars : 4.372e-03
: 99 : vars : 4.325e-03
: 100 : vars : 4.308e-03
: 101 : vars : 4.286e-03
: 102 : vars : 4.251e-03
: 103 : vars : 4.213e-03
: 104 : vars : 4.207e-03
: 105 : vars : 4.154e-03
: 106 : vars : 4.135e-03
: 107 : vars : 4.133e-03
: 108 : vars : 4.114e-03
: 109 : vars : 4.110e-03
: 110 : vars : 4.031e-03
: 111 : vars : 4.030e-03
: 112 : vars : 3.952e-03
: 113 : vars : 3.952e-03
: 114 : vars : 3.854e-03
: 115 : vars : 3.838e-03
: 116 : vars : 3.822e-03
: 117 : vars : 3.821e-03
: 118 : vars : 3.812e-03
: 119 : vars : 3.810e-03
: 120 : vars : 3.790e-03
: 121 : vars : 3.769e-03
: 122 : vars : 3.743e-03
: 123 : vars : 3.735e-03
: 124 : vars : 3.723e-03
: 125 : vars : 3.712e-03
: 126 : vars : 3.699e-03
: 127 : vars : 3.694e-03
: 128 : vars : 3.680e-03
: 129 : vars : 3.669e-03
: 130 : vars : 3.658e-03
: 131 : vars : 3.633e-03
: 132 : vars : 3.633e-03
: 133 : vars : 3.602e-03
: 134 : vars : 3.597e-03
: 135 : vars : 3.595e-03
: 136 : vars : 3.591e-03
: 137 : vars : 3.536e-03
: 138 : vars : 3.529e-03
: 139 : vars : 3.525e-03
: 140 : vars : 3.481e-03
: 141 : vars : 3.478e-03
: 142 : vars : 3.472e-03
: 143 : vars : 3.458e-03
: 144 : vars : 3.454e-03
: 145 : vars : 3.433e-03
: 146 : vars : 3.415e-03
: 147 : vars : 3.406e-03
: 148 : vars : 3.375e-03
: 149 : vars : 3.320e-03
: 150 : vars : 3.306e-03
: 151 : vars : 3.295e-03
: 152 : vars : 3.288e-03
: 153 : vars : 3.285e-03
: 154 : vars : 3.271e-03
: 155 : vars : 3.269e-03
: 156 : vars : 3.231e-03
: 157 : vars : 3.223e-03
: 158 : vars : 3.211e-03
: 159 : vars : 3.198e-03
: 160 : vars : 3.195e-03
: 161 : vars : 3.184e-03
: 162 : vars : 3.184e-03
: 163 : vars : 3.162e-03
: 164 : vars : 3.154e-03
: 165 : vars : 3.145e-03
: 166 : vars : 3.133e-03
: 167 : vars : 3.057e-03
: 168 : vars : 3.044e-03
: 169 : vars : 3.034e-03
: 170 : vars : 3.034e-03
: 171 : vars : 3.030e-03
: 172 : vars : 3.022e-03
: 173 : vars : 3.012e-03
: 174 : vars : 2.990e-03
: 175 : vars : 2.981e-03
: 176 : vars : 2.961e-03
: 177 : vars : 2.948e-03
: 178 : vars : 2.941e-03
: 179 : vars : 2.924e-03
: 180 : vars : 2.921e-03
: 181 : vars : 2.870e-03
: 182 : vars : 2.867e-03
: 183 : vars : 2.860e-03
: 184 : vars : 2.859e-03
: 185 : vars : 2.777e-03
: 186 : vars : 2.753e-03
: 187 : vars : 2.752e-03
: 188 : vars : 2.752e-03
: 189 : vars : 2.748e-03
: 190 : vars : 2.747e-03
: 191 : vars : 2.735e-03
: 192 : vars : 2.735e-03
: 193 : vars : 2.723e-03
: 194 : vars : 2.723e-03
: 195 : vars : 2.638e-03
: 196 : vars : 2.626e-03
: 197 : vars : 2.615e-03
: 198 : vars : 2.609e-03
: 199 : vars : 2.594e-03
: 200 : vars : 2.583e-03
: 201 : vars : 2.569e-03
: 202 : vars : 2.523e-03
: 203 : vars : 2.494e-03
: 204 : vars : 2.464e-03
: 205 : vars : 2.424e-03
: 206 : vars : 2.415e-03
: 207 : vars : 2.401e-03
: 208 : vars : 2.360e-03
: 209 : vars : 2.341e-03
: 210 : vars : 2.318e-03
: 211 : vars : 2.299e-03
: 212 : vars : 2.273e-03
: 213 : vars : 2.238e-03
: 214 : vars : 2.227e-03
: 215 : vars : 2.218e-03
: 216 : vars : 2.215e-03
: 217 : vars : 2.160e-03
: 218 : vars : 2.127e-03
: 219 : vars : 2.118e-03
: 220 : vars : 2.116e-03
: 221 : vars : 2.107e-03
: 222 : vars : 2.095e-03
: 223 : vars : 2.020e-03
: 224 : vars : 2.015e-03
: 225 : vars : 2.008e-03
: 226 : vars : 1.989e-03
: 227 : vars : 1.963e-03
: 228 : vars : 1.915e-03
: 229 : vars : 1.892e-03
: 230 : vars : 1.875e-03
: 231 : vars : 1.869e-03
: 232 : vars : 1.866e-03
: 233 : vars : 1.864e-03
: 234 : vars : 1.848e-03
: 235 : vars : 1.833e-03
: 236 : vars : 1.731e-03
: 237 : vars : 1.552e-03
: 238 : vars : 1.463e-03
: 239 : vars : 1.457e-03
: 240 : vars : 1.434e-03
: 241 : vars : 1.331e-03
: 242 : vars : 1.035e-03
: 243 : vars : 8.667e-04
: 244 : vars : 5.518e-04
: 245 : vars : 3.942e-04
: 246 : vars : 0.000e+00
: 247 : vars : 0.000e+00
: 248 : vars : 0.000e+00
: 249 : vars : 0.000e+00
: 250 : vars : 0.000e+00
: 251 : vars : 0.000e+00
: 252 : vars : 0.000e+00
: 253 : vars : 0.000e+00
: 254 : vars : 0.000e+00
: 255 : vars : 0.000e+00
: 256 : vars : 0.000e+00
: --------------------------------------
: No variable ranking supplied by classifier: TMVA_DNN_CPU
: No variable ranking supplied by classifier: TMVA_CNN_CPU
TH1.Print Name = TrainingHistory_TMVA_DNN_CPU_trainingError, Entries= 0, Total sum= 4.86809
TH1.Print Name = TrainingHistory_TMVA_DNN_CPU_valError, Entries= 0, Total sum= 7.50384
TH1.Print Name = TrainingHistory_TMVA_CNN_CPU_trainingError, Entries= 0, Total sum= 7.70545
TH1.Print Name = TrainingHistory_TMVA_CNN_CPU_valError, Entries= 0, Total sum= 6.58832
Factory : === Destroy and recreate all methods via weight files for testing ===
:
: Reading weight file: ␛[0;36mdataset/weights/TMVA_CNN_Classification_BDT.weights.xml␛[0m
: Reading weight file: ␛[0;36mdataset/weights/TMVA_CNN_Classification_TMVA_DNN_CPU.weights.xml␛[0m
: Reading weight file: ␛[0;36mdataset/weights/TMVA_CNN_Classification_TMVA_CNN_CPU.weights.xml␛[0m
Factory : ␛[1mTest all methods␛[0m
Factory : Test method: BDT for Classification performance
:
BDT : [dataset] : Evaluation of BDT on testing sample (400 events)
: Elapsed time for evaluation of 400 events: 0.00532 sec
Factory : Test method: TMVA_DNN_CPU for Classification performance
:
: Evaluate deep neural network on CPU using batches with size = 400
:
TMVA_DNN_CPU : [dataset] : Evaluation of TMVA_DNN_CPU on testing sample (400 events)
: Elapsed time for evaluation of 400 events: 0.0125 sec
Factory : Test method: TMVA_CNN_CPU for Classification performance
:
: Evaluate deep neural network on CPU using batches with size = 400
:
TMVA_CNN_CPU : [dataset] : Evaluation of TMVA_CNN_CPU on testing sample (400 events)
: Elapsed time for evaluation of 400 events: 0.0888 sec
Factory : ␛[1mEvaluate all methods␛[0m
Factory : Evaluate classifier: BDT
:
BDT : [dataset] : Loop over test events and fill histograms with classifier response...
:
: Dataset[dataset] : variable plots are not produces ! The number of variables is 256 , it is larger than 200
Factory : Evaluate classifier: TMVA_DNN_CPU
:
TMVA_DNN_CPU : [dataset] : Loop over test events and fill histograms with classifier response...
:
: Evaluate deep neural network on CPU using batches with size = 1000
:
: Dataset[dataset] : variable plots are not produces ! The number of variables is 256 , it is larger than 200
Factory : Evaluate classifier: TMVA_CNN_CPU
:
TMVA_CNN_CPU : [dataset] : Loop over test events and fill histograms with classifier response...
:
: Evaluate deep neural network on CPU using batches with size = 1000
:
: Dataset[dataset] : variable plots are not produces ! The number of variables is 256 , it is larger than 200
:
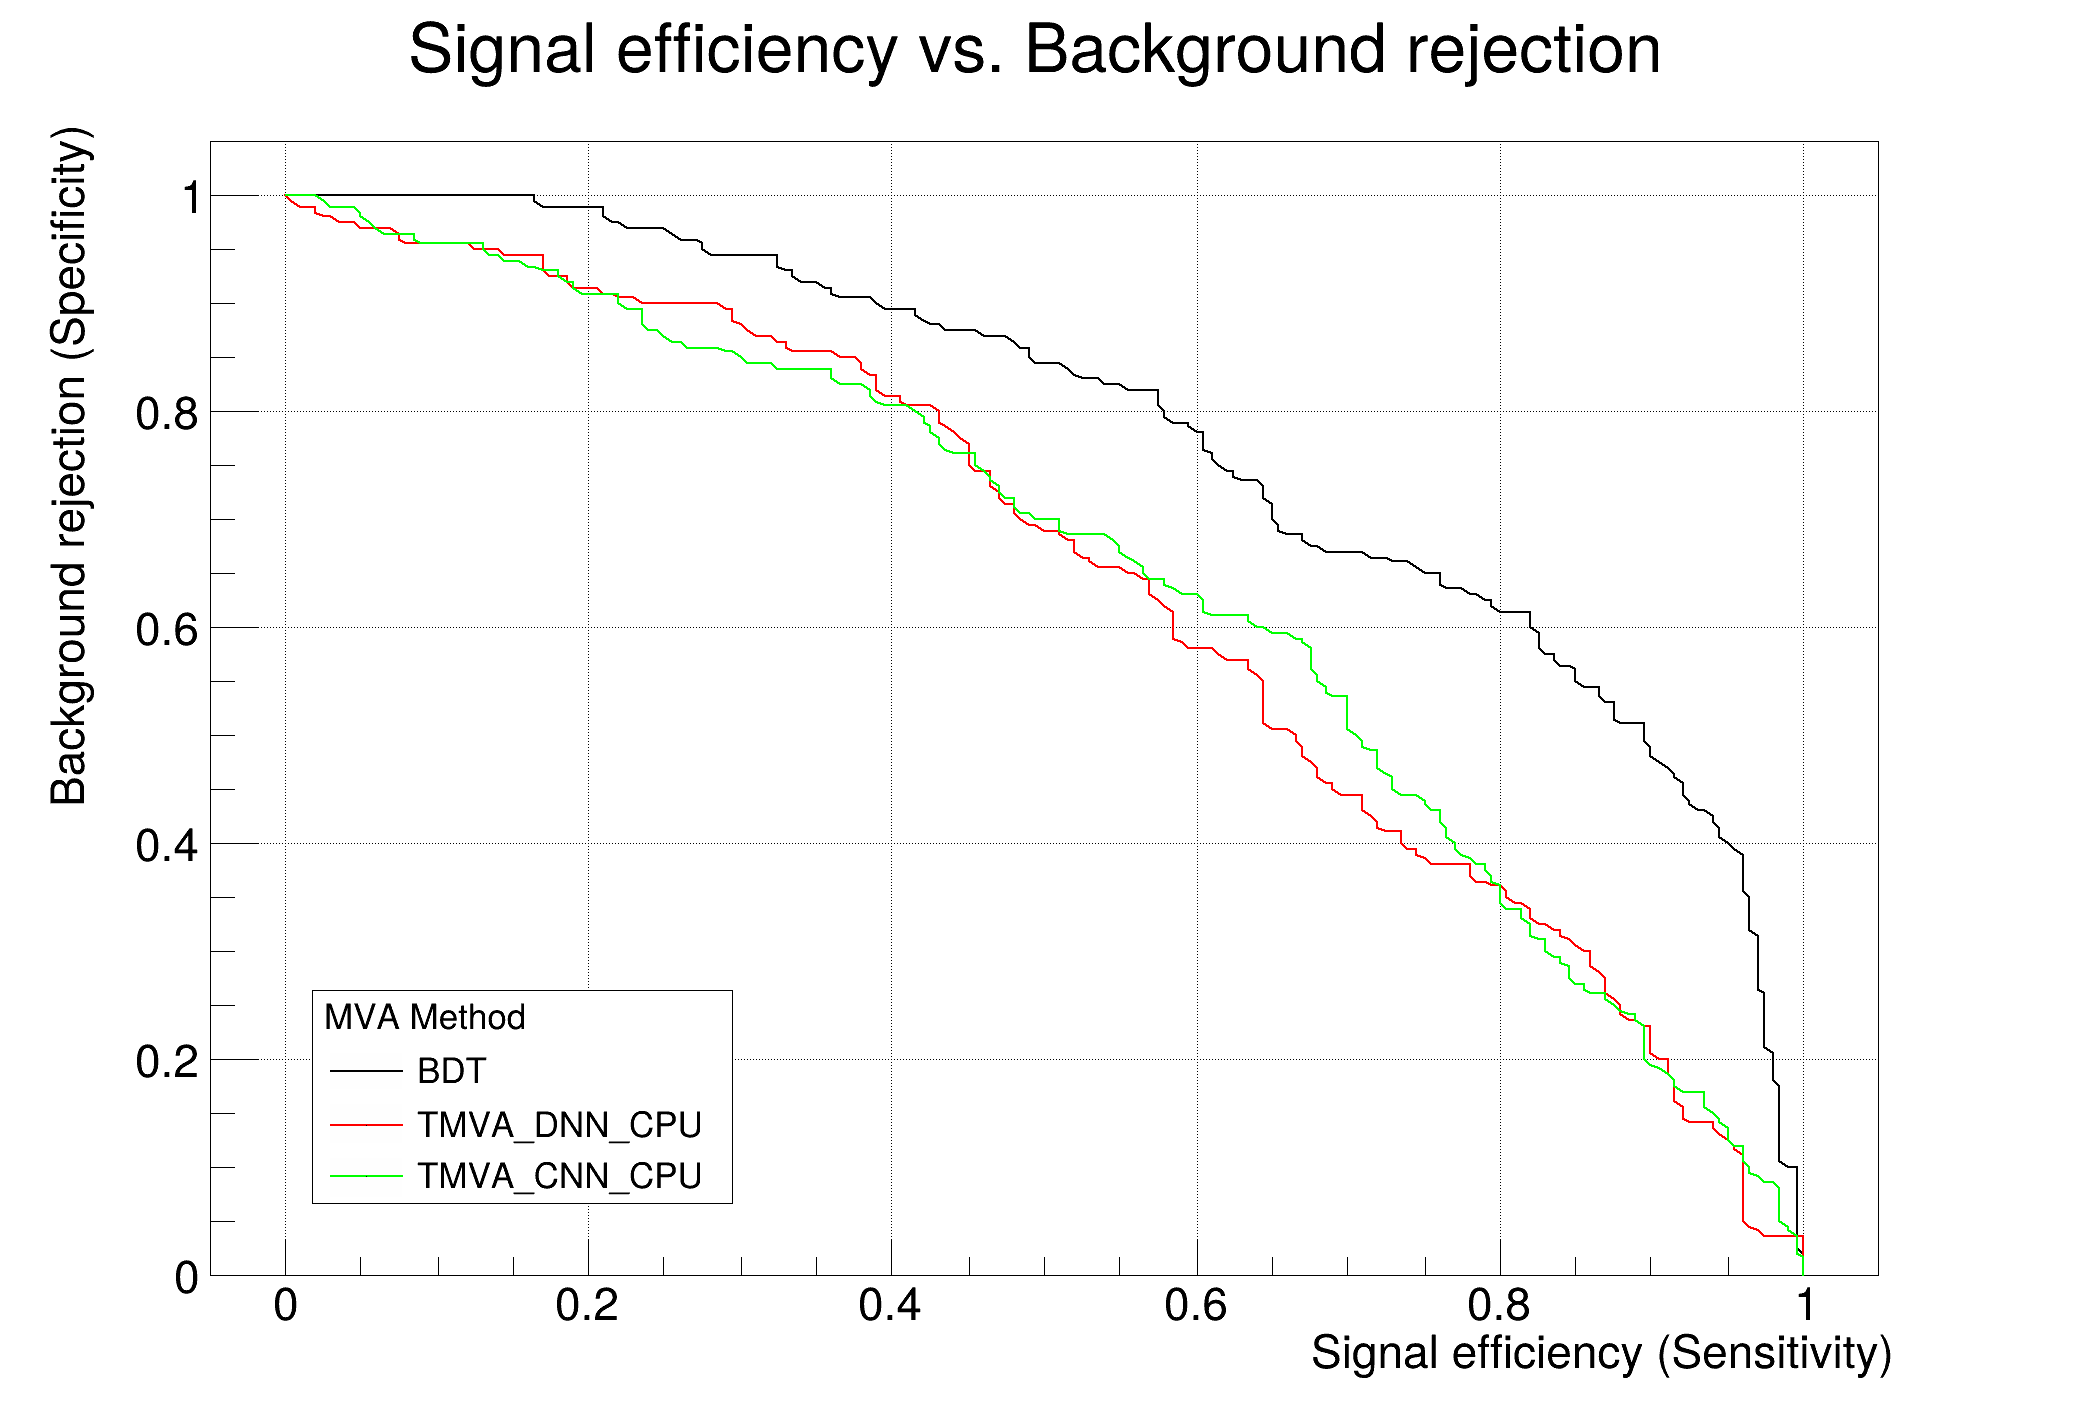
: Evaluation results ranked by best signal efficiency and purity (area)
: -------------------------------------------------------------------------------------------------------------------
: DataSet MVA
: Name: Method: ROC-integ
: dataset BDT : 0.796
: dataset TMVA_CNN_CPU : 0.775
: dataset TMVA_DNN_CPU : 0.656
: -------------------------------------------------------------------------------------------------------------------
:
: Testing efficiency compared to training efficiency (overtraining check)
: -------------------------------------------------------------------------------------------------------------------
: DataSet MVA Signal efficiency: from test sample (from training sample)
: Name: Method: @B=0.01 @B=0.10 @B=0.30
: -------------------------------------------------------------------------------------------------------------------
: dataset BDT : 0.205 (0.355) 0.428 (0.690) 0.740 (0.914)
: dataset TMVA_CNN_CPU : 0.035 (0.135) 0.420 (0.523) 0.702 (0.788)
: dataset TMVA_DNN_CPU : 0.020 (0.135) 0.210 (0.408) 0.475 (0.678)
: -------------------------------------------------------------------------------------------------------------------
:
Dataset:dataset : Created tree 'TestTree' with 400 events
:
Dataset:dataset : Created tree 'TrainTree' with 1600 events
:
Factory : ␛[1mThank you for using TMVA!␛[0m
: ␛[1mFor citation information, please visit: http://tmva.sf.net/citeTMVA.html␛[0m